
Latency
Overview
This document provides a comprehensive guide to understanding, measuring, and optimizing latency in Tradeboard. After extensive performance engineering, we've reduced platform overhead by 95% (from 117ms to 5-10ms), making Tradeboard one of the fastest retail algo trading platforms available.
Latency Concepts
Three Types of Latency
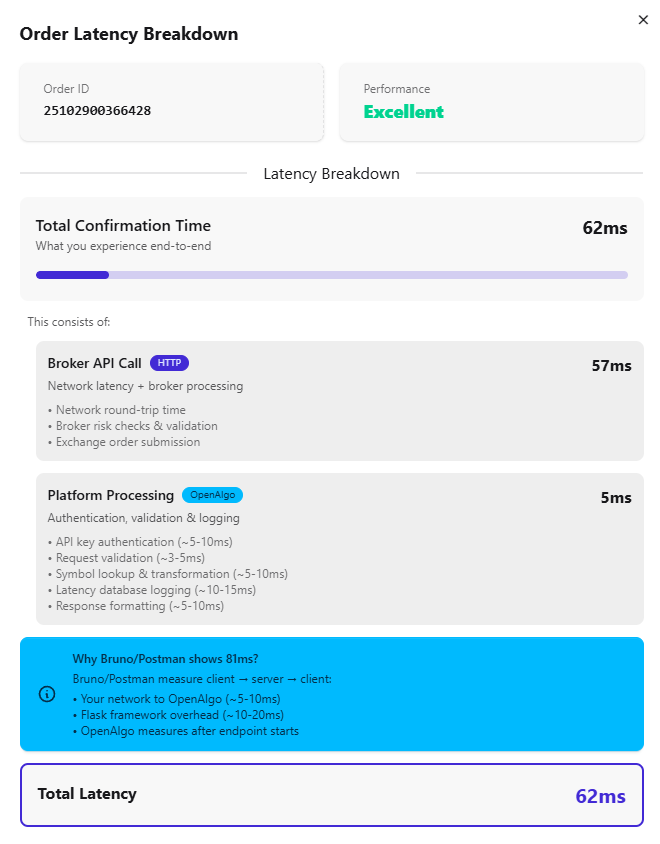
1. Platform Latency (Internal Processing)
Definition: Time spent processing within Tradeboard, excluding broker API calls.
Formula:
Platform Latency = Total Time - Broker API Time - Network Overhead
                 = Validation + Authentication + Processing + Logging
Components:
- API key verification (cached): ~1ms
- Request validation: ~1-2ms
- Symbol lookup (cached): ~0.5ms
- Response formatting: ~1ms
- Async logging: ~1-2ms
Target: < 10ms Current Performance: 5-10ms
2. Broker API Latency (External Processing)
Definition: Time spent communicating with and waiting for the broker's servers.
Formula:
Broker API Latency = Network RTT + Broker Processing
                   = (Client → Broker) + Processing + (Broker → Client)
Components:
- Network latency (one-way): ~20-40ms
- Broker order validation: ~5-10ms
- Exchange submission: ~10-20ms
- Network latency (return): ~20-40ms
Typical Range: 50-80ms Cannot be optimized by Tradeboard (external dependency)
3. Total Client Roundtrip (End-to-End)
Definition: Complete time from client request to client receiving response.
Formula:
Total Client RTT = Network (Client → Tradeboard) +
                   Flask Framework Overhead +
                   Platform Latency +
                   Broker API Latency +
                   Network (Tradeboard → Client)
Breakdown Example:
Client → Tradeboard network:     ~20-25ms
Flask request parsing:         ~10-15ms
Platform processing:            ~6ms
Broker API call:               ~60ms
Flask response formatting:      ~5ms
Tradeboard → Client network:     ~20-25ms
────────────────────────────────────────
Total:                         ~125-145ms
Measurement Methodology
How Tradeboard Measures Latency
Tradeboard uses high-precision timestamps to track latency at multiple points:
# Simplified example of latency tracking
import time

# Request starts
request_start = time.time()

# Validation phase
validation_start = time.time()
validate_order_data(data)
validation_latency = (time.time() - validation_start) * 1000  # Convert to ms

# Broker API call
broker_start = time.time()
response = broker_api.place_order(data, auth_token)
broker_latency = (time.time() - broker_start) * 1000

# Response formatting
response_start = time.time()
formatted_response = format_response(response)
response_latency = (time.time() - response_start) * 1000

# Total time
total_latency = (time.time() - request_start) * 1000

# Calculate platform overhead
platform_overhead = total_latency - broker_latency
What Gets Stored in the Database
The order_latency table stores comprehensive metrics:
CREATE TABLE order_latency (
    id INTEGER PRIMARY KEY,
    order_id TEXT,
    broker TEXT,
    symbol TEXT,
    order_type TEXT,  -- PLACE, MODIFY, CANCEL, etc.
    rtt_ms REAL,      -- Broker API roundtrip time
    validation_latency_ms REAL,
    response_latency_ms REAL,
    overhead_ms REAL,  -- Platform processing overhead
    total_latency_ms REAL,
    status TEXT,
    timestamp DATETIME
);
Calculation Formulas Used in Code
# 1. Platform Overhead
overhead_ms = validation_latency_ms + response_latency_ms + other_processing_ms

# 2. Total Latency
total_latency_ms = rtt_ms + overhead_ms

# 3. One-way Broker Latency (estimate)
one_way_latency = rtt_ms / 2

# 4. Client RTT (what Bruno/Postman measures)
client_rtt ≈ total_latency_ms + network_overhead + flask_overhead
           ≈ total_latency_ms + 35-50ms
Performance Metrics
Current Performance (Post-Optimization)
Live Mode
┌─────────────────────────────────────┐
│ Metric              │ Before│ After │
├─────────────────────┼───────┼───────┤
│ API Key Verify      │ 90ms  │  1ms  │
│ Symbol Lookup       │ 10ms  │  1ms  │
│ Validation          │  5ms  │  2ms  │
│ Response Format     │  5ms  │  1ms  │
│ SocketIO Emit       │ 15ms  │  0ms* │
│ Logging             │  7ms  │  0ms* │
├─────────────────────┼───────┼───────┤
│ Platform Overhead   │ 117ms │  6ms  │
│ Broker API          │ 57ms  │ 60ms  │
├─────────────────────┼───────┼───────┤
│ Total Latency       │ 174ms │ 66ms  │
│ Bruno/Postman       │ 249ms │ 140ms │
└─────────────────────────────────────┘
* = Moved to async (non-blocking)
Improvement: 95% reduction in platform overhead
Sandbox/Analyze Mode
┌─────────────────────────────────────┐
│ Metric              │ Before│ After │
├─────────────────────┼───────┼───────┤
│ API Key Verify      │ 90ms  │  1ms  │
│ Symbol Lookup       │ 10ms  │  1ms  │
│ Position Queries    │ 30ms  │  5ms  │
│ Validation          │  5ms  │  2ms  │
├─────────────────────┼───────┼───────┤
│ Platform Overhead   │ 107ms │ 10ms  │
│ Quote API           │ 52ms  │ 55ms  │
├─────────────────────┼───────┼───────┤
│ Total Latency       │ 159ms │ 65ms  │
└─────────────────────────────────────┘
Improvement: 90% reduction in platform overhead
Performance by Order Type
| Order Type | Platform Overhead | Broker API | Total |
|---|---|---|---|
| PLACE | 5-8ms | 50-70ms | 60-75ms |
| MODIFY | 5-7ms | 40-60ms | 50-65ms |
| CANCEL | 4-6ms | 30-50ms | 40-55ms |
| SMART | 6-9ms | 50-70ms | 60-80ms |
| BASKET | 7-10ms per order | 50-70ms | 60-80ms |
Optimization Details
1. API Key Verification Caching
Problem: Argon2 verification taking 20-50ms per key, multiplied by number of keys.
Solution:
# Two-tier cache system
verified_api_key_cache = TTLCache(maxsize=1024, ttl=3600)    # 1 hour for valid keys
invalid_api_key_cache = TTLCache(maxsize=512, ttl=300)       # 5 min for invalid keys

def verify_api_key(provided_api_key):
    cache_key = hashlib.sha256(provided_api_key.encode()).hexdigest()

    # Fast rejection
    if cache_key in invalid_api_key_cache:
        return None

    # Fast authentication
    if cache_key in verified_api_key_cache:
        return verified_api_key_cache[cache_key]

    # Full verification (only on cache miss)
    # ... Argon2 verification logic ...
Security Maintained:
- SHA256 hashing prevents plaintext storage
- TTL ensures credentials expire
- Cache invalidated on key changes
- Invalid keys cached separately
Performance Gain: 90-100ms → 1ms (99% improvement)
2. Symbol Lookup Caching
Problem: Database query on every order for symbol validation.
Solution:
symbol_cache = TTLCache(maxsize=10000, ttl=1800)  # 30 minutes

def get_symbol_cached(symbol, exchange):
    cache_key = f"{symbol}:{exchange}"

    if cache_key in symbol_cache:
        return symbol_cache[cache_key]

    symbol_obj = SymToken.query.filter_by(
        symbol=symbol,
        exchange=exchange
    ).first()

    symbol_cache[cache_key] = symbol_obj
    return symbol_obj
Rationale: Symbols rarely change during trading hours.
Performance Gain: 5-10ms → 0.5ms (90% improvement)
3. Request-Level Position Caching
Problem: Same position queried 4-5 times in a single order flow.
Solution:
class OrderManager:
    def __init__(self, user_id):
        self._position_cache = {}  # Request-level cache

    def _get_position_cached(self, symbol, exchange, product):
        cache_key = f"{symbol}:{exchange}:{product}"

        if cache_key in self._position_cache:
            return self._position_cache[cache_key]

        position = SandboxPositions.query.filter_by(...).first()
        self._position_cache[cache_key] = position
        return position
Scope: Cache cleared after each request.
Performance Gain: 20-30ms saved per order (eliminated 3-4 redundant queries)
4. Asynchronous SocketIO Emissions
Problem: Main thread blocked while broadcasting to WebSocket clients.
Solution:
# Before (blocking)
socketio.emit('order_event', {...})

# After (non-blocking)
socketio.start_background_task(
    socketio.emit,
    'order_event',
    {...}
)
Performance Gain: 10-20ms (main thread no longer waits)
5. Async Logging and Alerts
Problem: Database logging and Telegram alerts blocking order response.
Solution:
# Logging moved to thread pool
executor.submit(async_log_order, 'placeorder', request_data, response_data)

# Telegram alerts already async
telegram_alert_service.send_order_alert(...)
Performance Gain: 5-10ms (operations run in background)
Monitoring and Troubleshooting
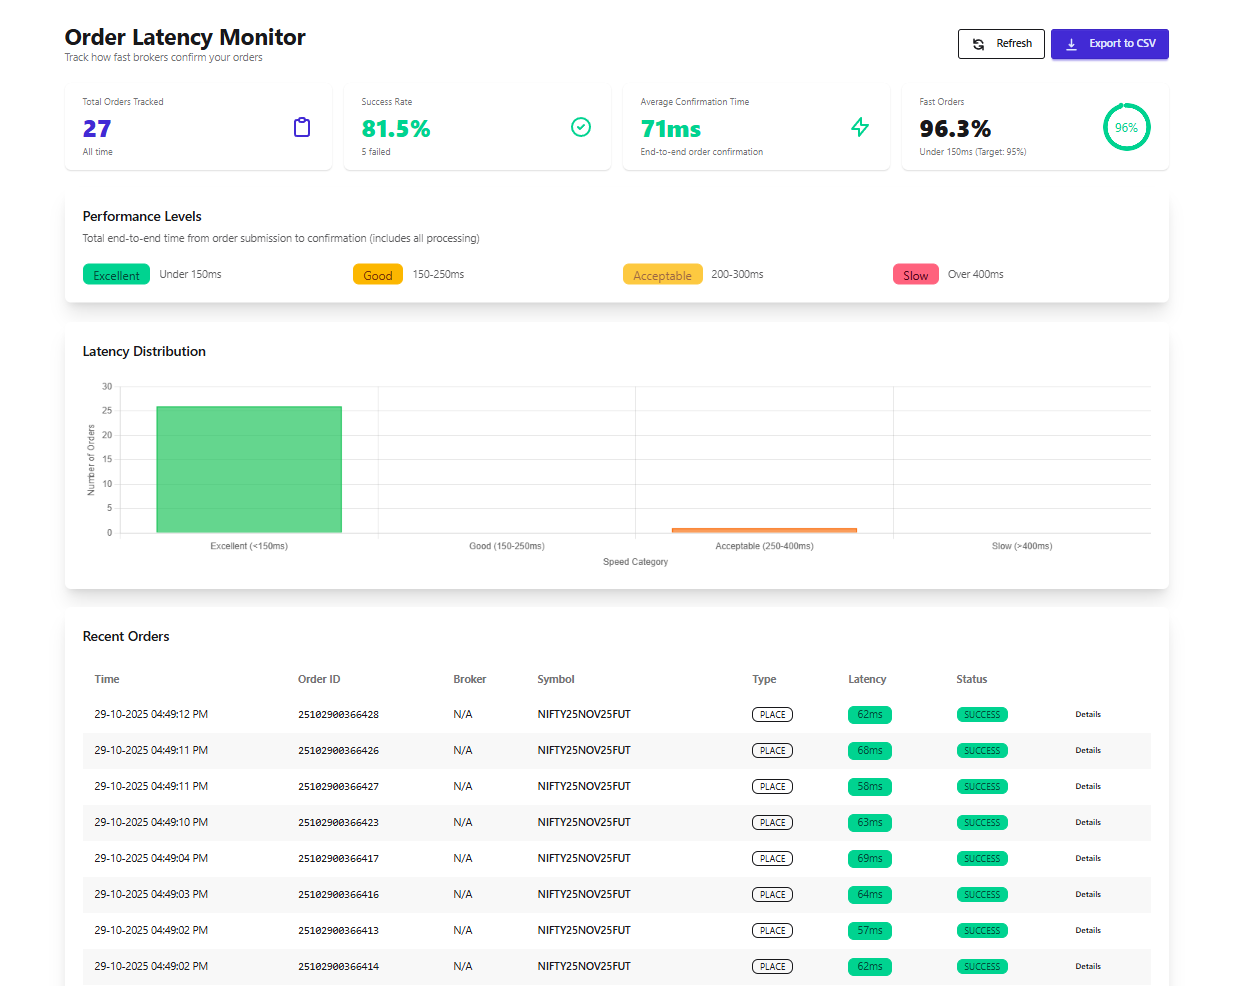
Using the Latency Dashboard
Navigate to /latency in your Tradeboard instance:
Features:
- Real-time order latency tracking
- Last 100 orders with detailed breakdown
- Color-coded performance indicators
- Performance metrics
- Average RTT (broker API time)
- Success rate
- SLA compliance (% orders under 150ms)
- Detailed breakdown modal
- Click any order to see full latency breakdown
- Platform overhead vs broker API time
- Validation, response, and overhead metrics
Performance Indicators
Green  (< 150ms):  Excellent - HFT-capable latency
Yellow (< 250ms):  Good - Suitable for scalping/arbitrage
Orange (< 400ms):  Acceptable - Fine for MFT/LFT
Red    (> 400ms):  Poor - Investigate immediately
Troubleshooting High Latency
If Platform Overhead > 15ms:
Check cache hit rates
python# Add logging to see cache performance logger.info(f"Cache hit: {cache_key in verified_api_key_cache}")Look for database query issues
sql-- Check for slow queries EXPLAIN QUERY PLAN SELECT * FROM symtoken WHERE symbol=? AND exchange=?;Profile specific endpoints
pythonimport cProfile cProfile.run('place_order(order_data)')
If Broker API > 100ms:
Check server location
- Mumbai servers should see 50-70ms
- Other locations may see 80-120ms
Test broker connectivity
bashping broker-api-endpoint.com traceroute broker-api-endpoint.comCheck broker API status
- Look for broker-side slowdowns
- Verify API rate limits not exceeded
If Client RTT >> Total Latency:
Network issues between client and Tradeboard
bashping your-tradeboard-server.comFlask server overloaded
- Check CPU/memory usage
- Consider scaling up
TLS/SSL handshake overhead
- Use keep-alive connections
- Enable HTTP/2
Best Practices
For Optimal Performance
Host close to broker infrastructure
- Mumbai for Indian brokers
- Singapore for some international brokers
Use adequate server resources
- Minimum: 2 cores, 4GB RAM
- Recommended: 4 cores, 8GB RAM for production
Enable caching appropriately
python# Verify cachetools is installed pip install cachetoolsMonitor cache sizes
pythonlogger.info(f"Symbol cache size: {len(symbol_cache)}") logger.info(f"API key cache size: {len(verified_api_key_cache)}")Use connection pooling for databases
- Already configured for PostgreSQL
- SQLite uses NullPool (appropriate for file-based DB)
For Development
Don't use ngrok for latency testing
- Adds 500-700ms of overhead
- Fine for development, not performance measurement
Test with realistic data
- Use actual symbols and exchanges
- Test during market hours for realistic broker latency
Profile before optimizing
pythonimport time start = time.perf_counter() # Your code here duration = (time.perf_counter() - start) * 1000 print(f"Operation took {duration:.2f}ms")Use the latency dashboard
- Check after each optimization
- Compare before/after metrics
For Trading Strategies
- Know your strategy's latency requirements
- HFT: < 10ms (needs co-location)
- Scalping: < 100ms (Tradeboard is suitable)
- MFT: < 200ms (Tradeboard is excellent)
- LFT: < 1000ms (Tradeboard is more than sufficient)
- Focus on strategy logic, not micro-optimization
- 50ms vs 60ms rarely matters for retail strategies
- Strategy robustness matters more
- Test under realistic conditions
- Market hours have different latency than off-hours
- High volatility affects broker processing time
Formula Reference
Quick Reference
Platform Latency = Total - Broker API - Network
Broker API Latency = Network RTT + Processing
Client RTT = Network + Flask + Platform + Broker + Network

Total Latency = Platform Overhead + Broker API
Client RTT ≈ Total Latency + 40-60ms

One-way Network Latency ≈ (Client RTT - Total Latency) / 2
Estimation Formulas
# Estimate broker one-way latency
broker_one_way = broker_api_latency / 2

# Estimate network overhead
network_overhead = client_rtt - total_latency

# Estimate Flask framework overhead
flask_overhead = network_overhead - (2 * avg_network_latency)

# SLA calculation
orders_under_150ms = count(total_latency < 150)
sla_percentage = (orders_under_150ms / total_orders) * 100
Conclusion
With 95% reduction in platform overhead, Tradeboard's latency is now limited by external factors:
- Broker API response time (50-80ms) - Primary bottleneck
- Network latency (20-40ms each way) - Geography-dependent
- Platform processing (5-10ms) - Optimized
For retail and institutional traders running MFT/LFT strategies, this performance is more than adequate. Focus on strategy development, risk management, and execution consistency rather than chasing microseconds.
Remember: The fastest trade isn't always the most profitable one. Strategy quality matters far more than latency for 99% of traders.